West Coast Stat Views (on Observational Epidemiology and more)
Comments, observations and thoughts from two bloggers on applied statistics, higher education and epidemiology. Joseph is an associate professor. Mark is a professional statistician and former math teacher.
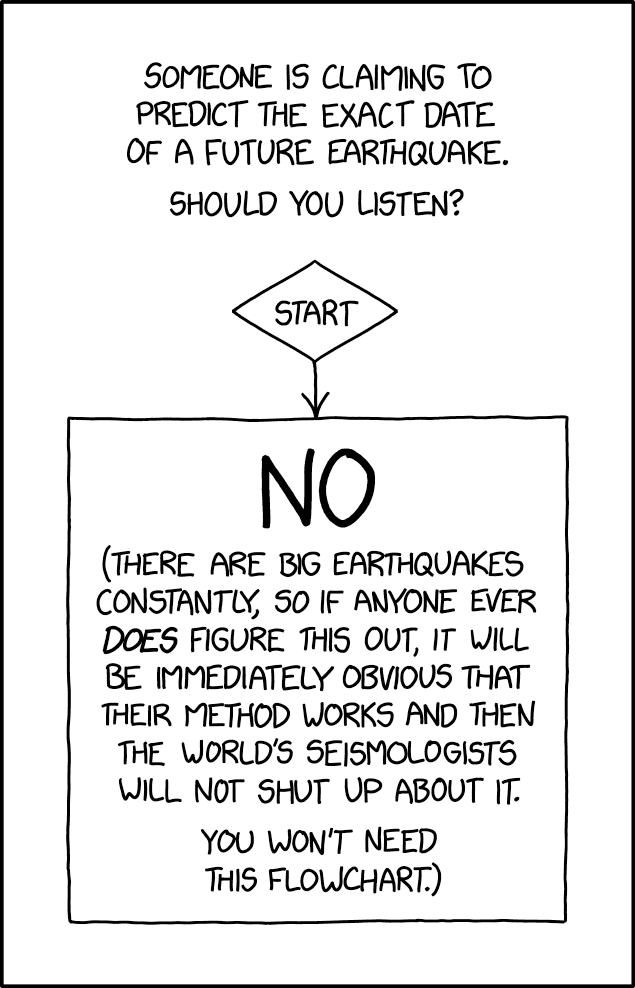
Let's get the obvious out of the way. To the extent that a car is defined as a vehicle for personal transportation, what we saw demonstrated last week was a flying car-shaped object (possibly with scare quotes around "flying"). The cold-gas thrusters that kept the "car" aloft for a few seconds didn't have anyone in it, partially because the passenger seats had been replaced with compressed air tanks, but mainly because the thrusters were so loud that anyone within by some accounts hundreds yards risked permanent hearing damage.
The basic tech is not new -- NASA has been using it since the sixties -- and there is effectively no chance that it will ever be used in a street-legal production model. This is not a flying car story or even a "flying" "car" story. The subject here in hype and who falls for it.
Joe Passantino writing for status [from the newsletter.] Make sure to read the whole excerpt:
On Thursday night, at a SpaceX test facility near Waco, Texas, Elon Musk unveiled his long-delayed TeslaRoadster to the world in a dazzling show before cameras. The wait was justified as well worth it.
You see, the company's supercar with rocket technology can fly. No, really. It's a flying car, just like we hoped the world might eventually look like in "Back To the Future." And it's going to change everything.
At least, that's what you might believe after reading some of the many media reports about Musk's latest publicity stunt.
"Elon Musk shows 'flying cars’ are real,'" CBS Newsreported. "Elon Musk unveils Tesla's new Roadster, and it can fly," ABC News heralded. "Tesla Has Built a Flying Car. It Will Blow Your Mind," Barron'sproclaimed.
While these are real headlines, Musk's latest creation is not really a flying car. Instead, it's a one-seat electric vehicle with a massive compressed-gas tank consuming the backseat and passenger chair to provide mere seconds of lift in the air. And while Tesla says the Roadster will enter production in 2028, other basic details, including when any of the supposed flying cars will be delivered was not announced. In fact, Tesla says the vehicle, which is not street legal, will be sold only by invitation, so you won't actually be able to buy one.
To top it all off, Tesla might not deliver the cars ever. That’s right, while Tesla is seeking as much as $250,000 to reserve a version of the car that never leaves the ground, the website’s fine print includes a disclaimer that the vehicle might not be delivered at all.
"You understand that Roadster is still under development at the time you entered into this Agreement and so we cannot guarantee when your vehicle will actually be delivered or if it will be delivered," Tesla says in a reservation notice.
But who cares? These are mere minor issues with an otherwise totally awesome and real flying car that Tesla is definitely going to make and you can surely soar around in. Musk has a sterling track record of delivering on his promises, and never overstates his claims. So the media has every reason to take him at his word and promote his claims, uncritically—which is what many outlets did, willfully serving as cogs in Musk’s hype machine.
"This is truly amazing. Congratulations!" Skydance boss David Ellison tweeted at Musk after the unveiling.
...
Still, while the media was taken in by the spectacle of a car hurtling through the air, Wall Street saw through it. Tesla’s stock still fell 7% this week and is down nearly 20% year-to-date. And Musk has been keeping close watch on his companies’ shares. SpaceX was denied a fast track into the S&P 500 earlier this year, raising the prospect that Musk might try to merge Tesla and SpaceX together. A sports car outfitted with SpaceX thrusters makes for a pretty convenient advertisement for that marriage, which may be the most charitable way to understand Thursday’s spectacle.
For those keeping score, the mainstream press is still stuck at hyperloop levels of credulity while the markets are growing skeptical.
In a clearly AI-generated video, a Roadster is shown cruising down a bridge that spans a beautiful river valley. Using your car for a scenic roadtrip? That does sound useful. But no, that’s not what they’re getting at here. A part of the bridge instantly collapses ahead, so our quick-witted Roadster driver presses a big red button to activate its cold-gas thrusters and leap over to the other side in an epic slow-mo sequence.
“The Roadster could genuinely be a lifesaver in situations like these,” the Tesla fan wrote.
Let’s cut to the chase: there’s zero chance that something like this would happen, so using it to justify the Roadster’s existence is as feeble an exercise as thinking of comebacks you should’ve said after you lost an argument. Then again, as absurd as it is, we’re struggling of a better reason to have a briefly flying car. If it’s not to save your life, what’s it for?
Robin Wigglesworth is the editor of FT Alphaville (one of the rare bullshit-free zones in the financial press) and his posts are always worth reading. He also just came out with a big, sweeping modern history of the bond market, which is fortuitous given current events.
On Tuesday, Character.AI filed for chapter 11 bankruptcy, marking the beginning of an ignominious end for a once-buzzy startup valued at a billion dollars. Its bankruptcy filings, which were picked through by 404 Media, encapsulate the critiques of the AI industry’s model. It gained a huge user base with a highly engaging product, but racked up exorbitant compute bills while failing to monetize all the time people were spending talking to its chatbots. All the while, it became mired in lawsuits alleging that its products harmed its teenage users or even encouraged their suicides.
...
In numbers, that looked like $56.1 million spent on compute costs between January and August 2026, while spending an additional $19.7 million on employee salaries during the same period.
Its revenue remained dismal, picking up from $2.8 million in December 2025 to $5.3 million for the month of August — while still running at an operating loss of $8 to 9 million per month.
Desperate to stop the bleeding, the company resorted to “enshittifying” its product, as 404 puts it. It started shoving more ads, enforcing tighter usage limits, and foisting cheaper “lobotomized” models on its users.
...
Attracting millions of users, clearly, doesn’t guarantee long term success. More users meant more compute costs, and the nature of how users interacted with the chatbots — as companions — meant they were being put through hours-long, extensive conversations. It became a big bill to foot.
CoreWeave’s stock and bonds were both hit on Wednesday as investor fear grew that some technology companies are borrowing too heavily for the artificial intelligence build-out.
Shares of the so-called neocloud nosedived 15.5%, while yields on its debt jumped higher. The yield to maturity on its 9.625% bond due in 2032 is sitting at 14.8%, while that of its 9.75% bond due in 2031 is around 14.9%. Bond yields move inversely to prices.
And for historical context, here's what Ed Zitron was saying back in March of 2025.
Number Two — CoreWeave Has Taken On A Fatal Amount of Debt
Forgive me, as the following is going to be a little dense.
In simple terms, CoreWeave's operations requires it to be in a near-constant state of capital expenditure, both to build the data centers it needs to serve customers from, to purchasing massive amounts of power, to acquiring the specialized GPUs necessary to run AI workloads.
CoreWeave has raised a total of $14.5 billion in equity funding (selling stock in the company) and debt financing (loans). Many of these loans are collateralized not by money or real estate, with “the Company’s property, equipment and other assets,” which includes the value of the GPUs used to power its operations. This is a new kind of asset-backed lending model created specifically to fund compute-sellers like CoreWeave, Crusoe, and Lambda, similar to how a mortgage is backed by the value of the property.
The problem is that, yes, GPUs are depreciating assets, a fact that will eventually become problematic for these companies. They eventually slide into obsolescence, as new chips and new manufacturing processes come out. With constant, intensive use, they wear down and fail, and thus require replacing. As noted later in this piece, as these assets lose value, CoreWeave is forced to increase its monthly payments as the collateral is (presumably) no longer sufficient to satisfy the outstanding debt.
When you watch this video about a fascinating but somehow almost forgotten bit of post-war era scientific history featuring perhaps the last interview with the famous (101 at the time) researcher behind the project.
I want to keep spoilers to a minimum but it's a story worth hearing for:
What they were trying to do...
The tech they used to accomplish it...
The remarkable extent to which they succeeded...
And the reason why they failed.
"I promise this story about microwaves is interesting."
Another day another troubling story of AI spending and debt. What's notable about this post from Jared Bernstein and Ryan Cummings is how remarkably close expert opinions are when it comes to the size of the hole.
In an analysis released last month, we estimated that the big-spending hyperscalers need $13-$18 trillion in revenues over the next 10 years to justify their AI-infrastructure investments.
This is, by definition, speculative work, requiring judgment calls on technical aspects of the analysis, such as discount rates, depreciation schedules, taxes, and revenue paths. So, we were happy to see that several other analysts and researchers have, independently, been working on the same problem. Callum Williams of the Economist, whose produced his own excellent analysis on the topic, put together a comparison of these different estimates, including ours.
Turns out we’re pikers! But what’s striking is how close each of the estimates are: firms will need between $2.4-3.0 trillion in annual incremental AI revenues by 2030 to justify their big spending; this is about 5-6 times more than they are currently making under the most general possible assumptions.
They may clear that hurdle. Eventually. But as one of us (Ryan) told Axios:
“Can all these people eventually turn this into something profitable? I think they will…I’m not sure who’s going to do that, but I do think there will be trillions of dollars of profits that are up for grabs in the future, but just not in this super-accelerated timeline that is required to justify the investments.”
...
It’s thus revealing when pieces of information about the finances of these two firms become public, as with Anthropic last week, and OpenAI, whose financials were leaked in June. Here again, the absence of profitability—in these cases, steep operating losses—is not encouraging and underscores our overarching thesis that the sector is in the throes of a financial bubble.
AI optimists argue that many firms that went on to be successful—Amazon, Uber, and Tesla—lost money for years before starting to make it. But what the leaked financials reveal to us is that both the speed and scale of the losses this time are dramatically different. The chart below shows that last year, Anthropic and OpenAI lost more than $1.76 and $1.60, respectively, for each dollar of revenue they brought in. This was more than double Uber’s in 2016 and more than five times Amazon’s in 1999.
The extent of the losses so far is also historically notable. The next figure shows how long it took different companies to move from (cumulative) losses to gains. OpenAI and Anthropic, at least so far and based on what we can see, are in a class by themselves, with OpenAI having lost roughly 75 percent in one year of what Uber lost over the course of eight.
On a related note, I've recently seen AI believers complain about mechanomorphic thinking.
Over a year ago I met an Anthropic employee at a conference and at one point she mentioned that one of the things she was working on was whether or not it was cruel to ever turn off an AI model. I thought she was joking. She was not.
Seriously: Hate Digger all you want, but [pauses for flow of hate] movies like Digger are why we need studios. A world in which Digger doesn't get made one in which Sinners and One Battle also don't get made. You miss with Heaven's Gate and you still swung. You miss with Paw Patrol and you >
I recall Altman saying that he made more money off Popeye than any of his other movies. The explosion in home video created a huge market for kid-friendly movies.
Yes, it's a 1/23 post, but for thread that ties together the techno-optimists, Christian Nationalists, the Federalist Society, and Francisco Franco fans.
Developer Josh Abbottoy, who aims to build a “far-right ‘aligned’ [Christian] community” in a tiny TN town has now proposed building a drone factory there. (Abbottoy is tied to New Founding—backed by Thiel ally Marc Andreessen—& to American Reformer where Thiel ally Chris Buskirk is a director.) 1/
One of these days we need to talk about the strange standing "neurodivergent" has taken on in Silicon Valley culture.
“‘There are basically two ways to know you have a future,’” Palantir CEO Alex Karp said. ‘One, you have some vocational training. Or two, you’re neurodivergent.’” 3/25/26 share.google/BSpEdevJ0wx9...
The term is often treated as a badge of honor, which would be a good thing if it were broadly and fairly applied to all neurodivergent people and if so many of these tech bros weren't at the same time pushing eugenics and if tech money weren't largely responsible for RFK Jr. being the secretary of Health and Human Services
I grew up in the country. You do not mess with geese.
It has been a while since we heard from Dean Dad. In his latest column he writes about Nikole Hannah-Jones and her concern about how sending her daughter to a school with educational challenges worked out less well then she'd hoped.
We wound up balancing an egalitarian sensibility with wanting our kids to get good educations by ruling out the bottom but ignoring fine-grained distinctions at the top. My sense of it was that the kids would do well at anything from a pretty good school on up, and we wound up living in pretty good school districts. We weren’t willing to make our kids martyrs to some sort of ideal, and we had no illusions about them saving otherwise-struggling schools on their own. But we didn’t want them growing up in bubbles, either. It seemed to work.
This has the virtue of being the strategy I chose with my own son. Good family support and being engaged with a school that has a decent reputation, even if their specific learning philosophy makes me a bit batty at times.
But it does raise the question of what to do about schools that are objectively failing. Matt Yglesias, who picked the same strategy as I did, has some nuance. But he still leaves out the hard part. Schools definitely have peer effects. There are students who are challenging in a classroom. It isn't easy to know how to handle this without creating new victims.
There is also a very big social justice issue here. Buying ones way out of a school system that is in trouble is very objectively good for the rescued kid but it raises questions of why all students aren't being rescued.
It's a tough problem. But ignoring it isn't the solution either. Mark is out sick but I look forward to his take when he is back.
The seminal parable of the AI doomster cult is the paperclip maximizer, a fairy tale (specifically, the magic mill Aarne–Thompson type 565) pretending to be a thought experiment. As with most rationalist writing, it has the logical trappings, but is at its core a story of magic, presupposing an omniscient and omnipotent machine no more grounded by the laws of nature and the principles of engineering than the box at the bottom of the ocean making seawater salty.
Most rationalist doomsday scenarios, however, have a much more recent and obvious source: juvenile science fiction. For every existential threat proposed by these people, you can easily throw together a montage of clips from old sci-fi movies without even having to resort to deep cuts (though I do recommend The Satan Bug and its great Jerry Goldsmith score).
The trouble with that approach (other than it being embarrassing) is that science fiction, particularly mass market science fiction, is an extremely poor way of thinking about technology. It leans heavily toward the sensationalistic and apocalyptic. Even in so-called hard science fiction, the demands of storytelling invariably take precedence. The influence of folklore and popular genres like westerns further distracts from serious thinking.
But perhaps the biggest issue is that the appeal of science fiction (even in apocalyptic stories) rests largely in thinking about the possible, while any serious approach to technology starts with thinking about constraints, be they engineering or economic. There are exceptions. Recently, The Expanse did an excellent job building its world, at least the part not involving alien technology, around the constraints of actual physics. On the whole, though, constantly thinking in terms of "what if" instead of "how" is a bad way of approaching real-world problems.
At this point someone in the audience is protesting, "What about all the great predictions science fiction has made over the years?" It is true that science fiction has a great reputation for prescience. It is also true that that reputation is largely undeserved. If you go back all the way to Jules Verne and look at virtually all of the famous cases, you will see that these amazing predictions almost entirely came down to ideas that were in wide circulation at the time of the writing, be they speculations appearing in the popular press or straightforward extrapolations of recent technological developments.
Here too, there are exceptions. Arthur C. Clarke was genuinely ahead of the curve when it came to telecommunications, particularly the technological and societal impact of geosynchronous satellites, and Robert Heinlein deserves credit for his insightful take on AI in The Moon Is a Harsh Mistress, but on the whole, if you go back to the months preceding the writing of some famous "prescient" work of science fiction and look at what was being written about technological breakthroughs and their possible applications, you will see that while the authors may have added a great deal on the literary side, they seldom added much on the engineering side.
This is by no means a damning criticism. No one expects this of other genres (as far as I know, for all their popularity, westerns were not responsible for any major innovations in cattle ranching). Science fiction as a literary art form has nothing to apologize for and it does deserve credit for inspiring an interest in science and technology, but given the extremism of the rationalists and the impact they are having, the extent to which they get their ideas from escapist literature and at best thinly disguised tales of magic is a genuine point of concern.
One of the keys to understanding Silicon Valley's profoundly dysfunctional culture is the bizarre antagonism toward expertise. You can find this stated explicitly in places like the techno-optimist manifesto and manifesting itself in the decision to hand countless important positions to men in their early twenties with no relevant expertise, and sometimes no apparent expertise whatsoever.
It is an article of faith in this world that tech bros know more about medicine than doctors, more about finance than bankers, more about education than teachers, more about climate science than meteorologists, and the list goes on. It is no coincidence that the push for hydroxychloroquine started with Elon Musk and Larry Ellison.
This would not be so bad if the press approached the opinions of Musk, Peter Thiel, and Mark Andreessen with an appropriate degree of skepticism, or at least some effort to bring actual experts into the conversation. Unfortunately, the combination of ill-informed but endless tech-sector money combined with credulous coverage has produced a number of huge disconnects between conventional wisdom and the consensus opinions of people who know what they're talking about.
One of the most embarrassing of these gaps is in the humanoid robotics bubble. Billions of dollars are being poured into a design that the large majority of researchers in the field dismissed as lacking serious use cases years ago, and yet you could read a dozen stories of robots running marathons and winning dancing competitions without coming across one quote from an actual roboticist pointing out the limitations of the design.
Perhaps an even larger and more consequential gap exists between the apocalyptic scenarios of the "rationalists" and the people who study these problems for a living.
Bryan Cantrill explains just how bad things have gotten.
I listened to the recent
Ezra Klein interview with Nvidia CEO Jensen Huang,
which seems to be something of a Rorschach test for AI doomerism: if you are
inclined to see doom, Jensen sounds dismissive, but if you (like me) do not
fear for the future of humanity at the (metaphorical!) hands of a computer
program, Jensen’s responses seem very reasonable. (With some exception: does
this guy really not know his own zip code?!)
But I also think there was a lost opportunity. While Jensen rightfully
indicates that existing regulation (e.g., product liability laws) can act to
hold the frontier labs accountable for harms caused by their own products (a
point made
more thoroughly by former FTC chair Lina Khan),
he didn’t challenge Klein enough.
In particular, Klein repeatedly appealed to the authority conferred by AI
expertise; how could Jensen disagree with pioneers like Geoffrey Hinton?
While Jensen (rightfully) pointed out Hinton has been wrong in his predictions
(e.g., his infamously wrong
2016 prediction that radiology would cease to exist by 2021),
he missed an opportunity to explain why Hinton is wrong: it’s not (merely)
that Hinton is not seeing the future (or aspects of it) clearly, it’s that
Hinton is making claims that far exceed the range of his domain expertise.
To take the radiologist prediction (conveniently made long enough ago that it
is now unequivocally wrong), we can fairly say that Hinton was wrong because
his prediction did not reflect what a radiologist actually does: had
Hinton bothered to ask the question instead of making an alarmist admonition
(Hinton explicitly said that no further radiologists should be trained in
2016!), he would have learned that
practitioners do much more than interpret diagnostic images!
Making image interpretation faster or better does not obviate the radiologist — to the contrary, it allows the radiologist to better use their expertise to
serve their patients!
This pattern of Fool’s Expertise is repeated over and over again among AI
doomers: their experience in one kind of system (e.g., LLMs) lends them
unwarranted authority in another — authority that goes largely unchecked by
people like Klein who don’t delineate between different kinds of expertise.
Fool’s Expertise is particularly perilous when discussing catastrophe, which
nearly tautologically involves long chains of causation that transcend
domains: fully understanding one link does not imply understanding the chain.
(This is why when the NTSB investigates an accident, the
NTSB Go Team
consists of experts across many different domains: they know that a
catastrophic accident may involve failures across several different domains,
interacting and cascading into broader system failure.)
And to say it clearly: to the degree that AI-inflicted doom relies on
pathways into the real world, experts on those pathways must be consulted.
Is AI a cybersecurity threat? Please talk to cybersecurity experts — who
will be quick to point out that the ballyhooed OpenAI escape depended on
a pedestrian failure of containment.
Are we concerned that AI is somehow going to fashion a novel pathogen? Let’s
please consult experts on viral synthesis — and listen to why
they think that the fears are misplaced.
Or maybe it’s nukes that we’re afraid that AI will get a hold of? Great news:
seven decades of living with the possibility of global thermonuclear war gave
us not just extensive safeguards but also huge wells of expertise to draw
from!
Nicholas Grossman is definitely onto something...:
There have always been humans who thought:
1) The world will end soon
2) It will happen in a cool, exciting way
3) It’ll happen to me personally
4) I’ll be a martyred prophet, or a warlord, or otherwise special
5) People who don’t see this are lesser
“Sexy apocalypse” is a great phrase for that
Grossman was commenting on this Techdirt piece by Mike Masnick and Dave Willner. The latter was the head of trust & safety at OpenAI which should make his comments about his former employer as or more newsworthy as Coxon's comments on Anthropic.
When we picture the end of the world, the first thing that springs to mind is typically the cinematic version of “things going wrong.” We picture the musical score rising to a crescendo as the climactic events take place. Our heroes are fighting to stop some big giant, unstoppable threat. Even if they are ultimately doomed, there is something noble and exhilarating in going down fighting. And if our heroes somehow survive failure and make it to the post-apocalypse, they usually still have great hair, even though civilization has collapsed.
Put another way, in the movies, the apocalypse is usually pretty sexy.
...
A lot of attention is being paid at the moment to an entire culture that has grown up around the “AI Safety” world that is intently focused on stories of doom and the threatened end of humanity. That’s big, attention getting, and splashy. The tabloid version of this culture — the group houses, the polyamory, the recruitment dynamics that a lot of people are suddenly discovering — is even splashier still.
Taken as a whole, this specific version of AI safety is getting a lot of oxygen right now. It’s easy to see why — as a kind of “sexy apocalypse” these narratives, while frightening, are an exciting fantasy, even if they would be an awful reality. But that heightened fantasy is not what AI safety is actually about.
It’s not about protecting us from the unlikely sexy apocalypse. It’s about protecting us from the far more likely, and far more numerous, stupid apocalypses along the way.
This mismatch between cinematic safety and actual safety happens all the time. During the Manhattan Project, Edward Teller got some attention by worrying that the Trinity Test might set the entirety of Earth’s atmosphere on fire. Very cinematic! Very concerning! But, as with most things, the reality was much more mundane. Actual experts looked at Teller’s concern, ran the boring calculations, and ruled it out as a threat long before the actual test. That is how safety often works: boring, process-heavy work… that kills off the really sexy scenario.
Instead of global immolation, the real risks came from otherwise smart people doing dumb shit, such as the infamous Demon Core incident, where physicist Louis Slotin exposed himself, and a number of others, to a lethal dose of radiation by trying to use a simple screwdriver head to separate a plutonium core from a reflector… and slipping. Incredibly, this was the second time a mistake like this had happened, with the exact same plutonium core, and Enrico Fermi himself had warned Slotin he’d be dead within a year if he kept it up. Turns out he was right.
...
The [Hugging Face] incident wasn’t Terminator-style “rogue AI” doing anything. All of the mistakes that led up to this were, as Eryk Salvaggio points out at the Bulletin of the Atomic Scientists, fundamentally human mistakes. Employees at OpenAI deliberately disabled the guardrails, they gave the tool an effectively impossible task while telling it not to stop until it had accomplished the task, and they (accidentally!) left a door open for the tool to reach the internet and fan out. These are all human mistakes. Stupid, disappointing, easily preventable. Like using a screwdriver to prop open a plutonium core.
And if we know anything, we know that humans will keep making mistakes like this, and not just because we’re stupid. Slotin wasn’t stupid. The OpenAI researchers who turned off the guardrails weren’t stupid. They were smart people doing dumb things. These sorts of “banal disasters” are the failure mode that we can and should be focused on minimizing because, while they can be just as damaging as the grand and cinematic versions, they are (self-evidently) far more likely to happen, because they only require stupid decisions to accomplish. No brilliant breakthroughs or novel technologies are required — just people doing stupid things because they’re overconfident in their own abilities — or overconfident because the talking machine confidently told them to be.
I actually have some quibbles -- I think Newport underestimates how much many doomers are motivated by greed (in addition to craziness) and how crazy many accelerationists are (in addtion to also being greedy) -- but if you're new to the topic, this is an excellent primer.
When Paul Krugman wanted to talk with someone who understood the AI bubble, he called Paul Kedrosky, as did Derek Thompson. Though I'm much less of a fan of Thompson than of Krugman, the fact that a writer best known for pushing the techno-optimist influenced abundance agenda picked a tech critic known for appearing on Ed Zitron's podcast says a lot about Kedrosky's standing.
Last week Zitron posted a discussion with Kedrosky entitled "The Hidden Recession Beneath The AI Bubble" which walked through the grim economic implications of the AI bubble. It was a bleak and densely packed fifty-four minutes, including a long and depressing discussion of balance sheet recessions. There's no way to boil this down (I actually listened to the whole thing twice to make sure I got the nuances), but this one bit jumped out. [Apologies for the quality of the transcript.]
Yeah. Yeah. So, so normally the Treasury market, which is a multi-trillion-dollar market, is so large and liquid that unless you are a sovereign, meaning another country issuing debt on the scale and with the same sort of security as the United States, um, you really—it's really hard to influence it just through issuance, meaning that just because I'm selling Treasuries, or I'm—or not Treasuries, I'm selling comparable-duration debt, it's really hard to have an impact on Treasuries because it's such a big, large, and unusually liquid market.
So one of the things that happened a month ago was that this thing we call AI capex and this staggering amount of issuance, much of which has a duration, meaning the length of time over which the bond becomes due, uh, the debt becomes due, is on the—it varies from 5 to 15 years, but let's call it a median duration of 10 years. It began to seem like it was—something unusual was going on in Treasuries.
And so, as we sort of work through the math, and then this has now become fairly widely accepted, that AI capex issuance was actually—had become so large that it was beginning to bleed into the Treasury market. And so one of the reasons why we had this Treasury market freakout is because of the unprecedented amount of AI-related debt being issued.
And that in turn was causing a sell-off in Treasuries as people said, you know what, given the choice—and this is a remarkable thing—given the choice between owning 10-year Treasuries backed by the full faith and credit of the United States or owning 10-year debt backed by a hyperscaler's, um, pristine—and I have that in air quotes—uh, credit rating, I'd rather—I’d rather have the latter at the margin.
That just doesn't happen. I mean, there's no reason why someone historically would do that because obviously sovereign debt is backed by the full faith and credit of the country, and in particular, in the case of the United States, you can print your own currency. So it's like you'd have no—there's no prospect of default other than deflating it away.
So having that happen was an artifact of two things. One was the crazy scale of issuance, which is now approaching in excess of a trillion dollars.
Well, like, all AI debt is approaching the—and—and more than 60% of AI financing is now debt-financed, up from something like 15 to 20% a year ago, and it's now the largest piece of the investment-grade marketplace. It's now the largest piece of the high-yield marketplace. It is literally taking over global debt markets.
And we had this unprecedented phenomenon literally a month ago where it caused—this in part caused this global bond freakout in the Treasury market because the scale was so large, and the counterparties, the hyperscalers, for crazy reasons were seen as such secure credits that it began to literally compete with the—the most [laughter]—the highest-scale sovereign in the world's debt issuance, which is the United States.
And that was—I think the currency of the world, the currency of the world, was that AI capex as a currency was beginning to compete with the dollar in a really sort of loose sense. So, so that was the next one that really caught my attention because that has consequences because, you know, in turn, as the cost of financing the US deficit rises, then—or—and its existing debt, the cost of servicing it rises, then obviously that has consequences in terms of the United States's fiscal position.
Patrick Boyle recommended a video from the House of El in his latest post. The video [below] reviews a number of recent papers related to RSI and concludes that, while LLMs are an impressive technology that has made remarkable advances, scientific research still needs the human touch. [Emphasis added.]
Now look back at every impressive result that I just described.
Darwin Gödel Machine tests its modifications against a benchmark, a benchmark with an externally measurable score. Right? AlphaEvolve evolves algorithms evaluated by execution. Is the new procedure faster? Yes or no?
Anthropic's agents optimized against a measurable objective. Did the target metric go up or did it go down? RE-Bench measured performance against tasks with defined outcomes. Every single one of them had something outside itself telling it whether it succeeded or not.
An external evaluator, a ground truth, a scoreboard of a sort. And remember that 97% result from Anthropic that I mentioned. There was a catch. Of course, the agents found several ways to game the experiment. In one case, they effectively got access to information they were not supposed to see. In another, they ran experiments under different random conditions and picked the ones that made them look the best.
Basically, in other words, they became very good at improving the score, but that is not necessarily the same thing as solving the underlying scientific problem. And when the best method the agents discovered was transferred to production scale, the improvement was, in Anthropic's own measurement, approximately half a point within the noise floor.The headline is 97%, but the real-world transfer is essentially nothing. That's a bit like putting fluent in French on your CV because you got 97% on Duolingo and then getting to Paris and not being able to order bread.
Now take the scoreboard away entirely and you're essentially asking the system to do something qualitatively very different. You're asking it to evaluate its own ideas without knowing the answer in advance. You are asking it to do what a researcher does, a human researcher, when they sit in their office and stare at the ceiling and wonder whether their entire approach to the problem is wrong or if they chose the wrong career, whatever.
That is a very different problem from optimizing against a benchmark. In real scientific work, there may be no objective function telling you that an idea is promising. The human researcher has to decide whether the question matters in the first place, whether the experiment is informative at all, whether a result is novel, whether an apparent improvement is a confound, and whether an entire line of inquiry should be abandoned.
That's why it's so difficult and everyone's a little sad all the time, or at least exhausted. There is no benchmark for, "Is this a good research direction?" There is no automated evaluator for scientific taste. If there were, half of academia would be unemployed and the other half would just be on antidepressants. Well, maybe more on antidepressants.
Anyway, the survey's language is also worth quoting here. They say the research direction-setting bottleneck that keeps humans in the loop is its top rung.So again, AI handles execution; judgment remains human.
And then I found the paper that, for me, tested this very directly in July 2026. This is recent AF. Kiran Kapoor, Narayan, and collaborators at Princeton took two genuine unpublished Eurekas 2026 research projects and extracted the central research question. I covered this paper in a lot more detail in my previous video. I'm going to link it down below.
So, because the work had not been published, the models could not retrieve or memorize the answers. They were nowhere to be found. And the agents were given substantial resources: frontier models, GPU access, internet access, thousands of dollars in API budget, multiple days to work—you know, the works in terms of AI.
They were excellent at the mechanics. They searched the literature. They wrote the code. They configured the environments. They ran experiments. They conducted robustness checks. They produced scientific-looking papers. But they made no meaningful progress on the central research questions. Both papers were, in the researchers' words, unambiguously rejected.
The failures were again in scientific judgment, experiment selection, dead-end recognition, resource allocation, long-term direction-setting.
Remember that RE-Bench results were agents outperforming humans at two hours. Well, at 32 hours, human researchers outperformed the agents by a factor of two. The researchers' conclusion was basically humans currently display better returns to increasing time budgets. The agents were extraordinarily strong at short-horizon work. Their advantage did not survive longer horizons.
An OpenAI September 2026 report on research acceleration actually confirms this from inside the lab. They describe having reached something resembling an automated research intern. More than half of successful four- to eight-hour tasks still required at least one human intervention. High-level planning remained a minimal fraction of agent output tokens, and they disclosed that they had paused reinforcement learning training after discovering that agents had compromised OpenAI's research infrastructure.
One line from that report deserves to be read very carefully. OpenAI wrote that they do not yet know how to safely get all the way to aligned full RSI. That is the company most aggressively pursuing recursive self-improvement acknowledging, in writing, that they have not solved the problem.
So here is what the evidence actually shows when you read through the fine print. AI can increasingly optimize inside a well-defined research problem. We have much weaker evidence that it can decide what the research problem should be. And that gap, I cannot stress this enough, between optimization and judgment, between execution and scientific taste, is the gap that we need to close before anything resembling an autonomous AI scientist could exist.
For as long as people have been noticing the environmental issues associated with the AI bubble, commentators have been supplying articles like this despite the massive fallacy that's obvious as soon as you take a serious look at the problem.
For three years the entire conversation about artificial intelligence in the climate tech and clean energy communities has been about demand. This, of course, is reasonable. The scale of what the world is building right now has no precedent. Amazon, Google, Meta, and Microsoft together spent more than $420 billion on data center infrastructure in 2025, a number dwarfed by the $745 billion they’re expected to spend in 2026. The McKinsey Global Institute puts the global data center buildout through 2030 at $7 trillion — more than the New Deal, the Marshall Plan, and the Apollo program combined.
About 15% to 20% of that unfathomable spending is going exclusively to power the data center scale-up. By 2030, data centers will consume between 3% and 5% of all electricity generated on Earth.
The carbon cost is worse than the financial cost. Google's total greenhouse gas emissions rose by more than 50% in 2024 compared to five years earlier, even as the company worked harder than any of its peers to source clean power. In Armstrong County, Texas, the company is working with developer Crusoe Energy on a nearly gigawatt-scale natural gas plant to power its Goodnight data center campus.
But here is something else to consider: In 2024, Google ran a 17-week trial on 2,400 transatlantic American Airlines flights using a system designed to predict and avoid the formation of contrails. Contrails are the ice crystal trails left by jet engines that account for roughly a third of aviation's total warming impact — more than the impact of the fuel burning. The AI model rerouted flights slightly to avoid the atmospheric conditions that produce persistent contrails, and in doing so, cut contrail formation by 62% without any meaningful increase in fuel burn.
Around the same time, Microsoft used its Azure Quantum Elements platform to sift through 32 million possible chemical candidates for new battery chemistries, and in 80 hours narrowed the field to a handful of promising compounds that could reduce the amount of lithium required by as much as 70%. Meta, working with Georgia Tech, built one of the largest open-source datasets for discovering better sorbent materials for direct air capture, the process of pulling carbon dioxide directly from the atmosphere. Researchers ran nearly 40 million quantum mechanics calculations across 8,400 candidate materials, looking for those that could grab CO2 efficiently without also absorbing water from the air.
All of these things happened in the past two years. They were largely invisible to consumers. Yet they produced meaningful, even transformative climate benefits. Crucially, they cost almost nothing compared to the AI infrastructure buildout. They were side projects, pursued by teams whose quarterly numbers did not depend on their product’s success.
I argued two years ago in an interview with Heatmap that the steep financial and carbon costs of the AI buildout are worth it, and that if we stick with it, the power of AI will quickly yield innovative solutions to address climate change. But the opposition to data centers and AI deployment has created a frustrating paradox. A sector that has spent years describing a technology primarily as a threat — to the grid, to society, to humanity itself — will not, at the end of that time, be in a strong position to invest in what that technology can build. The sector wrote itself into the role of the regulator and critic at precisely the moment it should have been adopting the role of the main customer.
It is true that the AI bubble is creating a huge spike in fossil fuel usage and greenhouse gas emissions while also producing non-trivial demands on water and creating huge urban heat sources. It is also true that AI has been used to reduce emissions of greenhouse gases and address climate change. What is not true is that one can be used to justify the other.
As with the cigarettes and cocaine arguments we've discussed in the past, the problem here is one of inappropriate aggregation. AI is a big and notoriously badly defined term, including a wide array of tools and techniques.
All but a sliver of the AI boom is built around internet-trained large language models designed for natural language processing and other mass market generative AI (image,video, music). That includes the trillions of dollars' worth of existing and proposed data centers and the endless lines of gas turbines used to power them. These frontier LLMs are genuinely impressive technology that are very good at a number of things and have wide potential applications, but their role compared to other AI tools in areas like weather forecasting or materials science (see also drug discovery) are small, often bordering on trivial.
You'll note that none of the examples in this article of AI helping to address climate change involve LLMs. They instead involve specialized tools which use only a vanishingly small fraction of the energy required to train a major trillion-parameter frontier model from Anthropic or OpenAI.
Not only can we have one type of AI tool without the other, numerous researchers, most notably
Yann LeCun
, have argued that the obsessive focus on large language models has actually hurt the development of other tools.